- Home
- Azure Data Engineer Training in Hyderabad with Placement Support at Version IT
Azure Data Engineer Training in Hyderabad with Placement Support at Version IT
- admin
Why Azure data engineers are in demand
Every company now collects more data than its teams can use. Orders, app clicks, payments and sensor readings pile up every day, and someone has to move that data, clean it and get it ready for reports and AI. That person is the data engineer, and on Microsoft’s cloud, that means Azure.
If you are looking for Azure Data Engineer training in Hyderabad with placement support, this article explains what the role involves, what you learn at Version IT, how placement support works, and what to expect after the course.
What does an Azure data engineer do?
An Azure data engineer builds and maintains the pipelines that carry data from source systems to a place where it can be analysed. In day-to-day work that means:
- Pulling data from databases, files, APIs and streaming sources
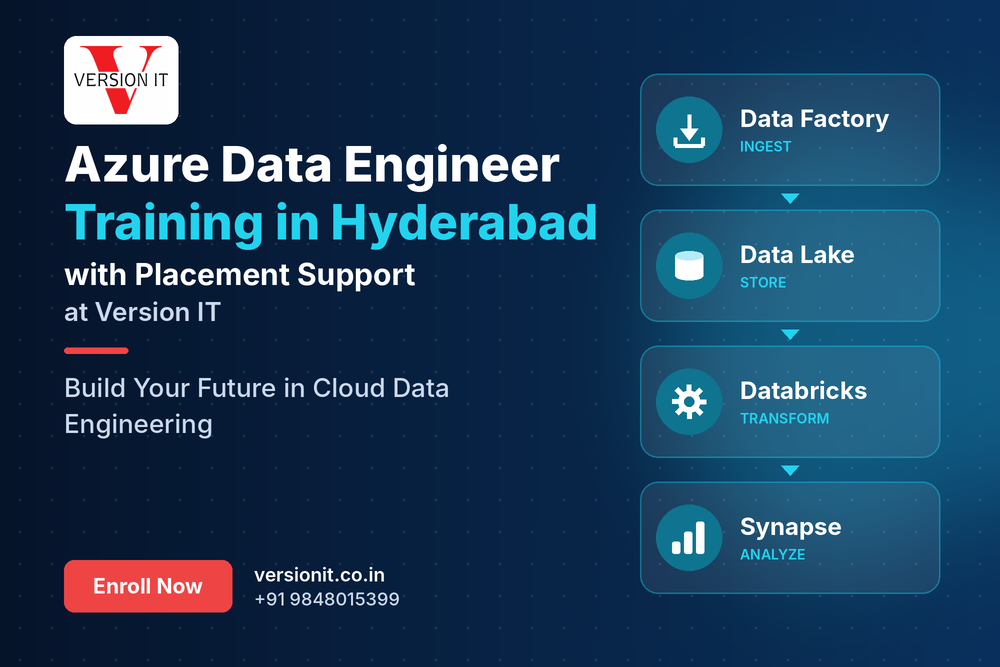
- Storing it in Azure Data Lake Storage
- Cleaning and transforming it with Azure Databricks or Synapse
- Loading it into models and warehouses that analysts use in Power BI
- Scheduling and monitoring pipelines, and fixing them when they break
The job mixes SQL, Python, cloud services and plain problem solving, which is why companies value people who can do it well.
Why learn Azure data engineering in Hyderabad?
Hyderabad is home to a large number of IT services companies, global capability centres and product teams, and many of them run their data platforms on Azure. That gives learners here a real job market to aim at, along with classmates, meetups and mentors who already work in data. Learning in the city also makes it easier to attend sessions regularly and to go for interviews in person once you are ready.
What you learn in the Azure Data Engineer course
The course starts with the basics and builds up to full data pipelines, so you are never lost halfway. The main modules are:
- Azure and cloud basics. Subscriptions, resource groups, storage accounts, security and access control.
- SQL for data engineering. Joins, window functions, CTEs and query performance basics.
- Python and PySpark. Python essentials first, then PySpark DataFrames for processing large datasets.
- Azure Data Factory. Pipelines, linked services, datasets, triggers, mapping data flows and incremental loads.
- Azure Data Lake Storage Gen2. Folder design, the bronze, silver and gold layers, and file formats like Parquet and Delta.
- Azure Databricks. Notebooks, clusters, Delta Lake, transformations and performance tuning.
- Azure Synapse Analytics. Dedicated and serverless SQL pools, loading data and querying it for reports.
- Streaming basics. Event Hubs and Stream Analytics concepts for near real-time data.
- Git, CI/CD and monitoring. Version control, deploying pipelines across environments, logging and alerts.
Real-time projects and hands-on practice
Learning tools one by one is not enough, so the course ties them together through end-to-end projects. A typical project ingests raw sales or banking data with Data Factory, lands it in the Data Lake, transforms it in Databricks through bronze, silver and gold layers, loads the result into Synapse and feeds a Power BI report.
Along the way you deal with the problems real teams face: schema changes, duplicate records, failed runs and incremental loads. Solving these is exactly what interviewers ask about, and it gives you a project you can explain with confidence.
Placement support: what it means
Let’s be honest about this. No institute can guarantee you a job, because an offer depends on your skills, your effort and the market. What good placement support can do is prepare you properly and put you in front of opportunities. At Version IT, the support focuses on:
- Resume building that highlights your projects and Azure skills
- LinkedIn profile guidance so recruiters can find you
- Mock interviews covering SQL, Spark, Data Factory and pipeline design
- Project explanation practice, so you can walk an interviewer through your pipeline step by step
- Job alerts and application guidance once you are ready to apply
The more you practise, the more this support helps you.
Who can join this course?
You do not need a data background to begin. The course suits:
- Fresh graduates in engineering, B.Sc, BCA or MCA who want a cloud career
- Software developers and testers who want to move into data
- SQL, ETL, SSIS or Informatica professionals shifting to the cloud
- Data analysts who want to learn the engineering side
- Professionals returning to IT after a break
Basic SQL knowledge helps, but it is not mandatory. Python and the cloud concepts are taught step by step.
Career roles after the course
Once you finish the training and build your projects, you can apply for roles such as:
- Azure Data Engineer
- Data Engineer
- Cloud Data Engineer
- Big Data Engineer
- Analytics Engineer
Job descriptions for these roles usually list SQL, Python or PySpark, Azure Data Factory, Databricks and Synapse together. That is the same set this course covers, so your skills line up with what recruiters search for. If you already work in ETL or BI, this training can also help you move into a more senior engineering role.
Why choose Version IT for Azure Data Engineer training
Many courses stop at slides and a demo. What matters is how much you practise and how well your doubts get cleared. At Version IT, the training is built around:
- Practical-first classes. You build pipelines in almost every session.
- Step-by-step learning. Each topic builds on the last, so beginners can follow and experienced professionals stay engaged.
- Project work. End-to-end projects you can show to employers.
- Interview preparation. Common Azure, SQL and Spark questions, plus guidance on presenting your project.
- Doubt support. Questions get answered, not postponed.
Start your Azure Data Engineer journey today
Data keeps growing, and companies need people who can turn it into something useful. If you want structured, hands-on Azure Data Engineer training in Hyderabad with placement support, Version IT is a good place to start.
Visit versionit.co.in or call +91 9848015399 to ask about batch timings and the demo class, and take your first step into cloud data engineering.
FAQ’s:
- What does Azure Data Engineer training cover?
This training covers the fundamentals of data engineering, including building data pipelines on the Microsoft Azure platform. Candidates will learn to gather data from varied sources and move it to Azure Data Lake for storage purposes and then obtain that data through various processing mechanisms such as Databricks or Synapse to prepare reports and perform analytics.
Who can attend the Azure Data Engineer training conducted by Version IT?
People intending to switch careers into IT, whether those may be fresh graduates, developers, or IT professionals can take the course, and any person who wishes to join it would be accepted even without having any previous background in the data discipline.
- Do I need to have some programming skills to be able to go through the course?
No. All essential knowledge for the training process is taught from the basis elements of Python, PySpark and SQL programming.
- What are the tools and topics covered in this course?
This course offers a training program on the use of the following tools: Azure Data Factory, Azure Data Lake Storage, Azure Databricks, Azure Synapse Analytics, SQL, Python, and PySpark, Delta Lake, and Git and CI/CD principles.
- Do the Version IT guarantee job placement after completing the course?
No institute can provide the guarantee of a job because it can depend on your abilities, work, and the job market. Version IT provides placement assistance that includes preparedness in resume writing, mock interviews, project clarification practices, assistance in job application process.
What are the types of projects that I will be involved in?
You will create complete end-to-end pipelines, for instance, by collecting raw data using Data Factory, saving it into the Data Lake, converting it with the help of Databricks, uploading it into Synapse, and linking it with a Power BI report. These projects will equip you with practical and useful information to discuss during interviews.
- What positions can I apply for after finishing the course?
After the completion of the course you will be ready for such positions as Azure Data Engineer, Data Engineer, Cloud Data Engineer, Big Data Engineer or Analytics Engineer. The knowledge and skills obtained during the training can help existing ETL/BI professionals apply for higher engineering positions.
Enquiry Form
Recent Posts
Azure Data Engineer Training in Hyderabad with Placement Support at Version IT
Advanced Cyber Security Training in Hyderabad for IT Professionals
Data Science Training in Hyderabad at Version IT – Build Skills for Tomorrow’s Technology
Best Cyber Security course with AI in Hyderabad, for industry- professionals